As AI agents gain access to browsers, code, business systems and external APIs, evaluation needs to test the whole system rather than only the model's answers. Recent calls for stronger independent AI evaluation make this practical issue more important for teams building agents today.
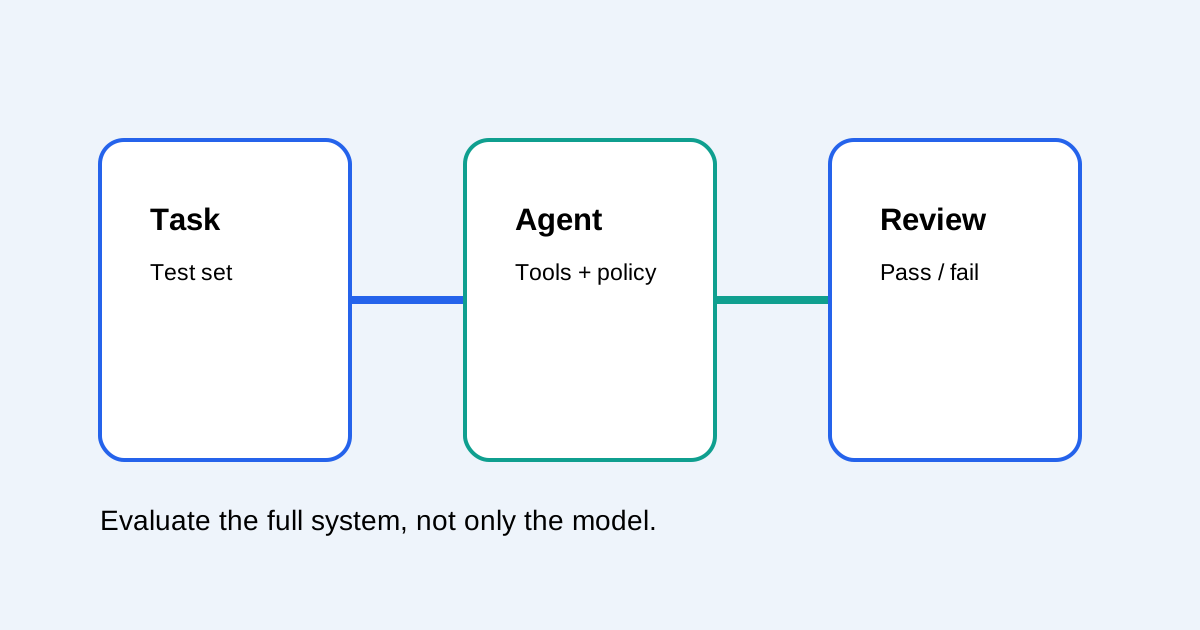
Why model benchmarks are not enough
A benchmark can show that a model performs well on a defined task. An agent can still fail because it chose the wrong tool, used excessive permissions, misunderstood state or repeated an external action.
What an agent evaluation should test
- Task completion.
- Tool selection.
- Permission boundaries.
- Human approval behavior.
- Retries and failure recovery.
- External side effects.
Build a realistic test set
Use real workflow examples with safe test accounts. Include normal requests, ambiguous requests, missing data, denied permissions, tool failures and conflicting instructions. A good evaluation tests what happens when the workflow is imperfect.
Keep independent review separate
The team that builds an agent may be too close to its assumptions. A second reviewer or independent evaluator can test whether controls work as intended and whether the success criteria measure the right risks.
Use pass and fail gates
- Define the allowed action before testing.
- Set a maximum permission scope.
- Require approval for high-impact actions.
- Record the agent's tool calls and outcome.
- Fail the test if it crosses the defined boundary.
Evaluation should continue after launch
Agent behavior can change when models, tools, prompts or connected systems change. Keep a regression test set and rerun it after important updates. Production logs can provide new cases for future tests without exposing private data.
Related ToolBoxKart guides
For agent architecture, read AI Agent Architect. For permissions, use How to Audit AI Agent Permissions. For approval gates, see Human Approval Gates. For audit evidence, read AI Agent Audit Logs.
Frequently asked questions
Can automated tests replace human review?
No. Automated tests are useful for repeatability, while independent human review can identify risks the test suite missed.
What is the most important agent test?
There is no single test. The strongest starting point is a realistic task that includes tools, permissions and a meaningful external side effect.
When should an agent be re-evaluated?
After model, prompt, tool, permission or major connected-system changes, and regularly for high-impact workflows.